Personal · 2026-06 → 2026-06
CSV Cleansing ETL
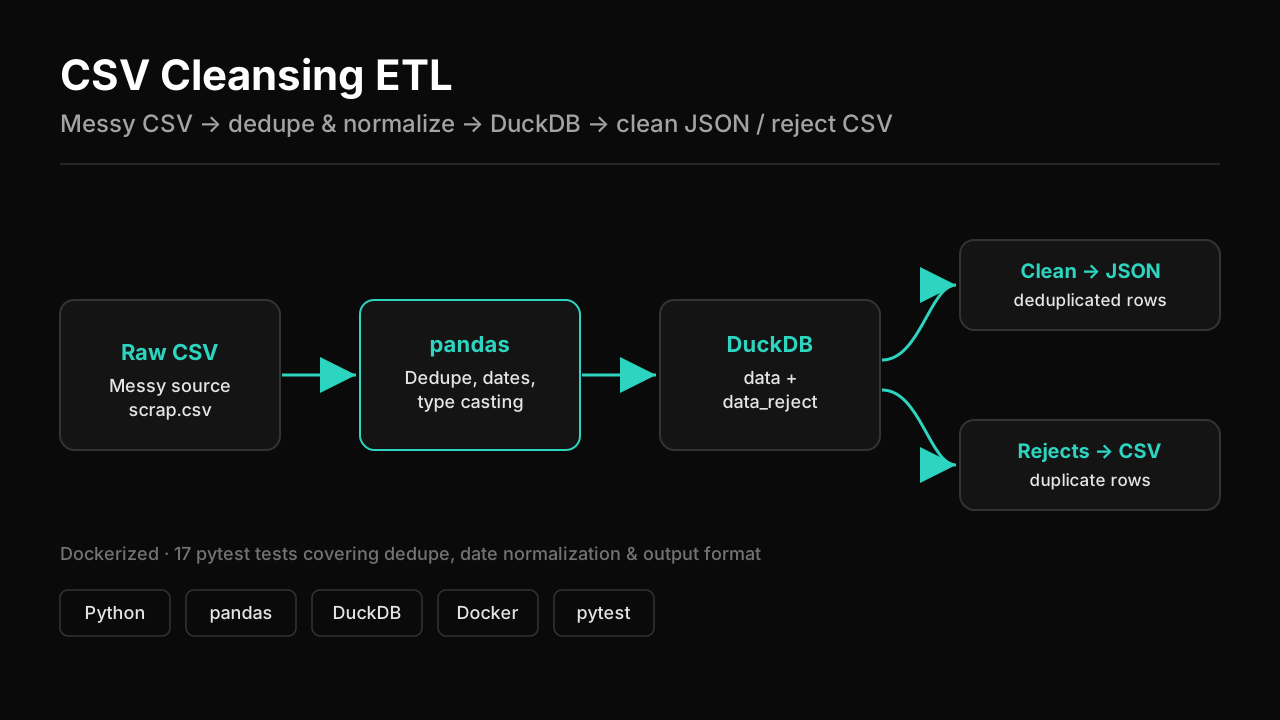
A Python ETL pipeline that reads a messy CSV, deduplicates and normalizes the rows, loads clean and rejected records into separate DuckDB tables, and exports the results to JSON and CSV. Dockerized and covered by 17 unit tests.
PythonpandasDuckDBDockerpytest
A self-initiated data engineering project focused on the fundamentals of a clean, testable ETL pipeline rather than a large stack.
The pipeline reads a raw CSV, deduplicates by ID (first occurrence wins), normalizes dates and casts types with pandas, then loads clean rows into a data table and rejected duplicates into a data_reject table in DuckDB. Clean records are exported to timestamped JSON and rejects to CSV.
What I built
- Built an extract-clean-load pipeline in Python with pandas and DuckDB, separating clean and rejected records into distinct tables.
- Implemented deduplication, date normalization (DD/MM/YYYY → ISO), and list-field parsing with structured logging.
- Containerized the workflow with Docker and docker-compose, mounting source/target as volumes for host output.
- Wrote 17 pytest unit tests covering deduplication logic, date normalization, type casting, and output file format.